Microsoft runs Phi-3-mini offline on an iPhone 14 at over 12 tokens per second
Microsoft introduced Phi-3-mini on April 22, 2024, a 3.8-billion-parameter model trained on 3.3 trillion tokens. The technical report puts it at 69 percent on MMLU and 8.38 on MT-bench, which the authors say rivals models such as Mixtral 8x7B and GPT-3.5.
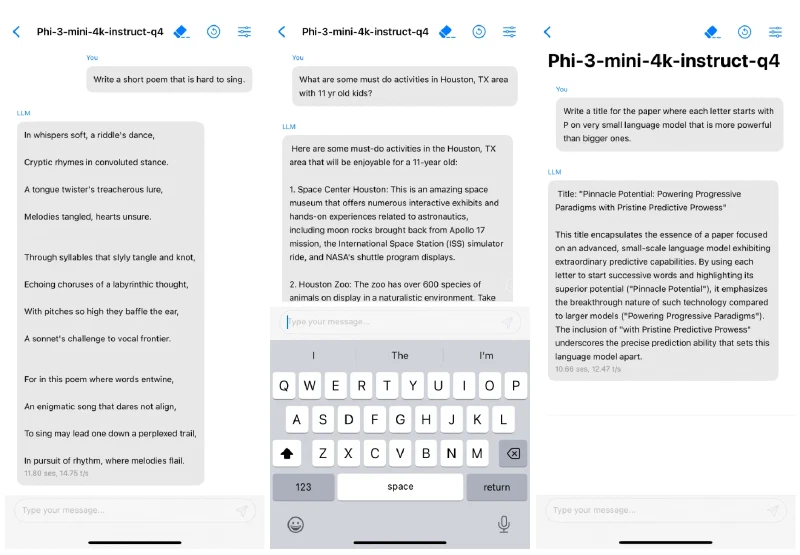
Quantised to 4 bits the model occupies about 1.8 GB, small enough for a phone. The report describes the test directly.
We tested the quantized model by deploying phi-3-mini on iPhone 14 with A16 Bionic chip running natively on-device and fully offline achieving more than 12 tokens per second.
The same report covers two larger siblings, Phi-3-small at 7B parameters and Phi-3-medium at 14B, both trained on 4.8 trillion tokens. Microsoft reports 75 percent on MMLU for the small model and 78 percent for the medium one.