Hugging Face trains SmolLM2 at 135M, 360M and 1.7B on up to 11T tokens
Hugging Face released SmolLM2 on October 31, 2024, a second generation of its small language models at 135M, 360M and 1.7B parameters. The company trained the 1.7B model on 11 trillion tokens, against 1T for the first SmolLM at the same size, and its model cards put the 360M model at 4T tokens and the 135M at 2T.
The mixture combines FineWeb-Edu, DCLM and The Stack with datasets Hugging Face curated for this run, which its paper from February 2025 names as FineMath for mathematics, Stack-Edu for code and SmolTalk for instruction tuning. That paper states the 1.7B run used a multi-stage schedule that held the highest quality maths and code data back for the final tenth of training, from 10T to 11T tokens, while the 360M and 135M models trained in a single stage on a mix kept consistent throughout. Hugging Face fine-tuned the instruct versions on SmolTalk and then tuned them further on ranked answer pairs from UltraFeedback.
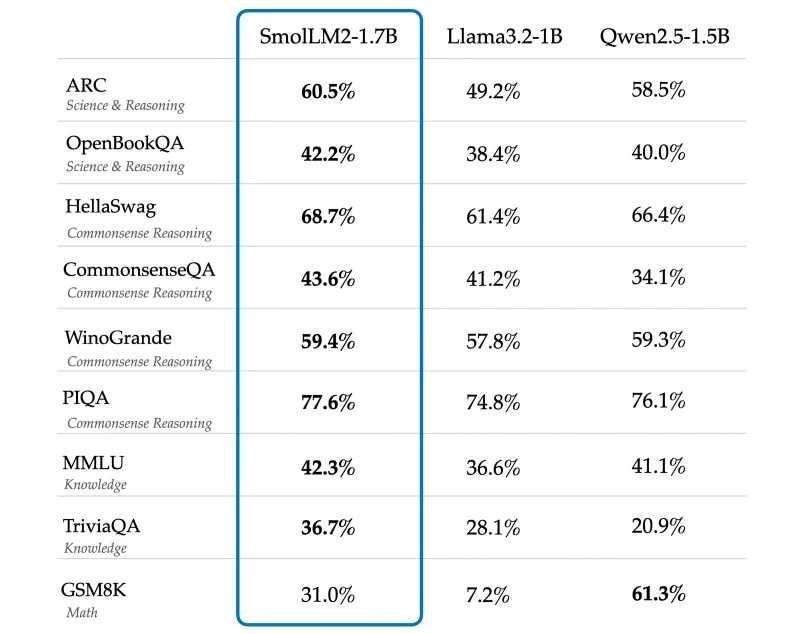
Hugging Face reports the 1.7B base model at 60.5 on ARC against 49.2 for Llama 3.2 1B and 58.5 for Qwen2.5 1.5B, 36.7 on TriviaQA against 28.1 and 20.9, and 19.4 on MMLU-Pro against 11.7 and 13.7, all run zero-shot with its own lighteval harness and printed in the model card. The instruct version scores 56.7 on the IFEval instruction-following test against 53.5 for Llama 3.2 1B Instruct and 47.4 for Qwen2.5 1.5B Instruct, while Qwen2.5 stays ahead on the MT-Bench chat test at 6.52 to 6.13. At the smaller sizes Hugging Face compares the 360M model with Qwen2.5 0.5B, reporting 53.0 against 45.4 on ARC and 16.9 against 4.3 on TriviaQA, and publishes no third-party comparison for the 135M model.
The weight files run 269 MB for the 135M model, 724 MB for the 360M and 3.42 GB for the 1.7B in bfloat16, and Hugging Face uploaded 4-bit ONNX builds the same day at 118 MB, 273 MB and 1.11 GB, plus a 4-bit GGUF of the 1.7B instruct model at 1.06 GB. The repository says the models run locally through llama.cpp, MLX, MLC and transformers.js. All six checkpoints carry an 8k context window and the Apache 2.0 license.
Update, November 27, 2024. Hugging Face published a browser chat demo that runs the 1.7B instruct model through transformers.js and ONNX Runtime Web on WebGPU, with no server call after the download. Its local inference guide adds runnable code for llama.cpp, MLX and MLC, and lists the models on Ollama and in the PocketPal-AI phone app.