Stability AI releases StableLM Zephyr 3B for edge devices
Stability AI released StableLM Zephyr 3B on December 7, 2023, a chat model with 3 billion parameters that the company aims at edge devices and hardware without the compute of dedicated high-end systems. Stability calls the model 60% smaller than 7B models and reports an MT-Bench score of 6.64 and an AlpacaEval win rate of 76.00%.
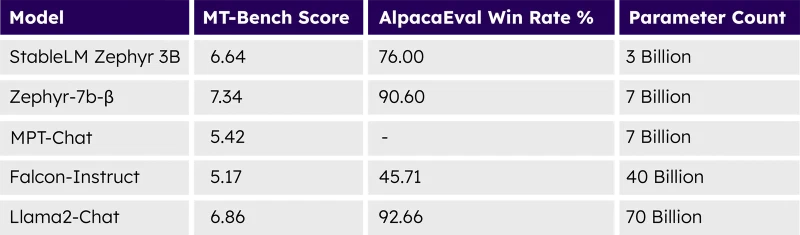
Both numbers are Stability’s own, measured on two evaluations the company links from the announcement. MT-Bench scores answers to open-ended questions with a larger language model acting as judge, and AlpacaEval measures how often a judge prefers a model’s reply over a reference answer. In the table Stability published with the model card, the 3B model sits above Falcon-Instruct at 40B parameters, which scored 5.17 on MT-Bench, and MPT-Chat at 7B with 5.42, and below Zephyr-7b-beta at 7.34 and Llama2-Chat at 70B with 6.86.
The model extends Stability’s earlier StableLM 3B-4e1t and borrows its training pipeline from Hugging Face’s Zephyr 7B, according to Stability. Stability first ran supervised fine-tuning on the UltraChat, MetaMathQA, Evol Wizard and Capybara instruction datasets, then aligned the result with direct preference optimisation, which trains a model on pairs of preferred and rejected answers instead of on correct answers alone. That second stage used UltraFeedback from the OpenBMB research group, a set of 64,000 prompts with model responses.
Stability put the weights on Hugging Face and linked an example notebook for tuning the model’s speed. The release is not open source. Stability states that it ships under a non-commercial community licence permitting non-commercial use, and tells anyone who wants the model in a commercial product to contact the company for separate terms.